How Vervali Load Tests Shopify Stores Before Black Friday
How Vervali load tests Shopify and Shopify Plus stores before Black Friday: the Shopify rules, what gets tested, when to start and what it costs.
Vervali tests fairness across protected groups, runs explainability checks and produces documented evidence for a model review board. We report the trade-off when the fair choice and the accurate choice differ, and we do not decide your risk appetite. The full model pack is on AI and machine learning testing.
ISO/IEC 17025:2017Accredited testing laboratory
CMMI Maturity Level 3The process is written down and repeats
ISO 9001:2015Quality management

ISO/IEC 27001Information security
What is tested, and what you receive at the end of it.
Whether the model behaves differently across groups it should not, with results reported for every group and subgroup you name, not only the overall average.
A single metric can hide a slice, so we report several fairness measures side by side and show exactly where they disagree with each other.
Some differences appear only at a chosen operating point, so we test fairness at the threshold you actually use in production, not a default cut-off.
Whether a decision can be defended to a customer or a regulator, using feature attribution, worked examples and the contents of a model card.
When the fair choice and the accurate choice differ, we report the trade-off in plain terms. We do not decide your risk appetite for you.
The slice that failed, the examples, the trade-off and what was not tested, written so a board can read it without a data scientist.
Need fairness and explainability evidence a review board can read?
Free Model ReviewFairness is one slice of model validation. These are the neighbouring packs.
The wider pack: accuracy, calibration, drift, robustness, data leakage and LLM output, with fairness as one slice. See AI and machine learning testing.
Independent validation of the model under review against held-out data you control, with results a board can read. See model validation testing.
Continuous checks on live inputs and outputs, so fairness that held at launch does not quietly fail later. See data drift testing.
Ongoing monitoring after launch and retraining when it is warranted rather than reflexive, so the model keeps behaving as it was validated. See AI model monitoring and retraining.
Already know the model and the groups? A QA lead can scope the pack.
Book a CallThe checks change with the model type, and we say so in the design if one is outside what we can evidence.
Checked as a black box: an endpoint or a scored file, a held-out set you control and the groups that matter. Training code is not usually required.
Classifiers, rankers and unsupervised systems each get checks suited to their type, and we say in the design if one is outside what we can evidence.
Whether the model treats groups differently, and whether a refusal or an answer can be defended. Hallucination and grounding are on AI and machine learning testing.
Three Vervali AI builds, sector named. They show Vervali has built and validated models at that scale and were not fairness-only jobs.
Financial services · KYC deepfake detection
Manual review was the bottleneck on identity. A detection model for know-your-customer cut that load: 70% less manual review at 75% detection accuracy. Whether the model could be defended sat in that pack.
70% less manual review 75% detection accuracyAI calling engine · lead qualification
An AI calling engine, built and validated by Vervali. After: 35% more qualified leads and a 28% shorter sales cycle. The checks were whether the engine actually qualified the lead.
35% more qualified leads 28% shorter sales cycleOperations · real-time SOP image detection
A real-time image detection system for standard operating procedure compliance, built and validated by Vervali. The check was whether the system caught the SOP miss on the floor.
From one model to evidence a review board can read.
Share the Model and Groups
Tell us the model, the groups that matter and the decision it supports, with a held-out set you control.
Get the Fairness Pack
We agree the fairness measures, the operating point and the explainability checks, and what is out of scope.
Start With a Model Review
A free review of one model, for one hour, is the first look. Most engagements land at $25 to $49 an hour blended, and price follows the groups and checks.
Get the Evidence
The failed slices, examples, the trade-off and what was not tested, 9am to 1pm Eastern with delivery from India.

OUR BLOGS
How Vervali load tests Shopify and Shopify Plus stores before Black Friday: the Shopify rules, what gets tested, when to start and what it costs.
Playwright testing rates at Vervali: $25 to $49 an hour typical, automation engineers $20 to $50, test architects $45 to $80, delivered from India.
How Vervali tests a SaaS startup's product: what to test first, when to outsource, manual or automation, the monthly cost at published rates, and how the free pilot…
Vervali offers test automation as a service: framework, suite, CI integration and maintenance on a monthly allocation, from India with a 9am to 1pm Eastern overlap.
Vervali publishes what Shopify and ecommerce testing costs: hourly rates by role, monthly billing for a dedicated tester or retainer, a fixed price for a pre-peak lo…
Every path through a use case becomes at least one test case. A worked bank-transfer example shows the test table, and ISTQB's 2023 and 2025 syllabus changes explain…
What a soak test is, how it differs from load, stress and spike tests, how long to run it, the metrics that decide a pass, and how JMeter, k6 and Gatling hold a load…
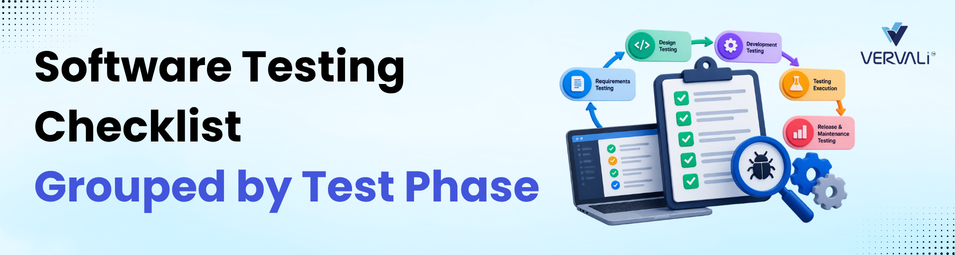
This software testing checklist groups every item by the phase of the test process it belongs to, marks the items teams routinely skip, and shows how to wire the lis…
Our Expertise


Trusted by 150+ Leading Brands

A Strong Team of 275+ QA and Dev Professionals

Worked across 450+ Successful Projects
 Email Us
 Call Us
From flawless code to flawless quality - we design, develop, and test digital solutions that deliver real results.